Run DeepSeek Behind Claude Code, Codex, and Other Coding CLIs
The cheapest way to find out whether DeepSeek fits your work is the client you already have open, Claude Code or Codex. Both take it as the model provider, and the editor and the commands stay as they are. ⚡
Claude Code
For Claude Code:
$env:ANTHROPIC_BASE_URL="https://api.deepseek.com/anthropic"
$env:ANTHROPIC_AUTH_TOKEN="sk-YOUR_DEEPSEEK_KEY"
$env:ANTHROPIC_MODEL="deepseek-flash[1m]"

claude
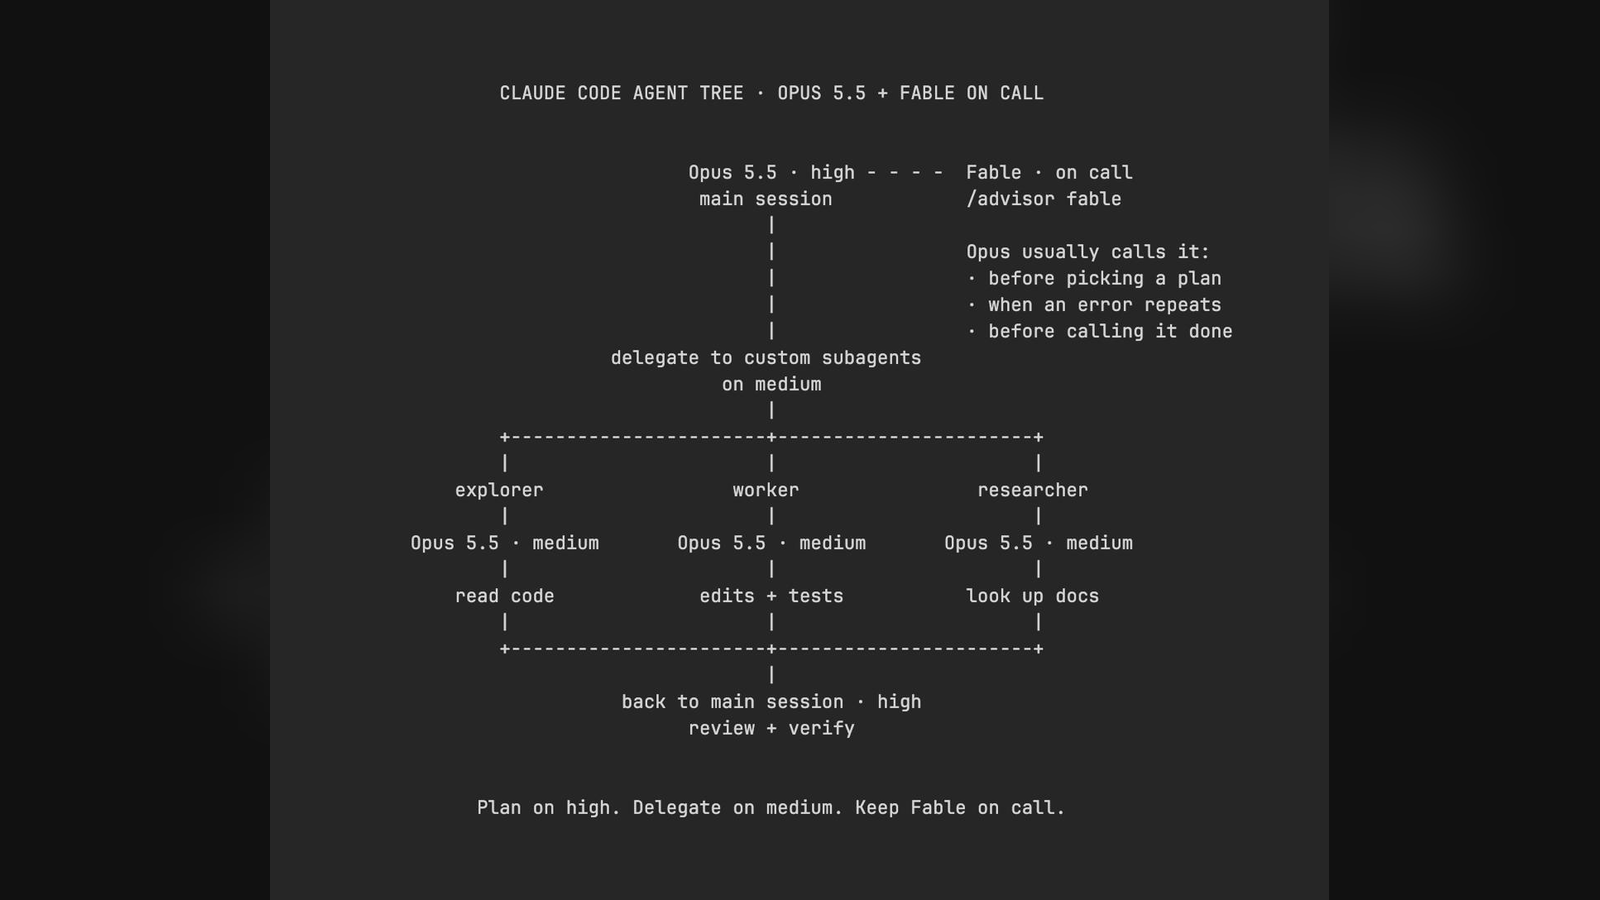
The published block also maps the default model slots and the subagent model. Those variables belong to one terminal window, which makes the setup easy to walk back.
Codex
irm https://cdn.deepseek.com/api-docs/codex-deepseek-setup-en.ps1 | iex

codex
Codex reaches DeepSeek over the Responses API, and that script writes the provider section, the model catalog and a backup of what it replaced.
OpenCode
OpenCode takes DeepSeek from inside its own interface: /connect for the key, /models for Flash or Pro.
Aider
setx OPENAI_API_BASE "https://api.deepseek.com"
setx OPENAI_API_KEY "sk-YOUR_DEEPSEEK_KEY"

aider --model openai/deepseek-flash
Aider edits the repository directly and commits as it goes, so a rollback is a Git operation.
LiteLLM
LiteLLM puts one local endpoint in front of DeepSeek, Claude, GPT and Gemini, with fallback, visible spend and a budget.
Ollama
ollama run deepseek-coder:6.7b
An 11 GB card handles DeepSeek Coder 6.7B and the 7B and 8B R1 distills, and 14B only in 4-bit and slow.
Why DeepSeek Flash instead of Claude Sonnet 5 or GPT-5.6 Terra?
DeepSeek publishes two rates per million tokens, and off-peak is half of peak:
Flash, off-peak   $0.15 input (cache miss)   $0.60 output
Flash, peak       $0.30 input (cache miss)   $1.20 output
Pro, off-peak     $0.66 input (cache miss)   $1.98 output
Pro, peak         $1.32 input (cache miss)   $3.96 output
The standard rung at the two providers a coding CLI reaches for by default:
Claude Sonnet 5   $2 input    $10 output
GPT-5.6 Terra     $2 input    $12 output
Flash vs Claude Sonnet 5   ~7-17x cheaper
Flash vs GPT-5.6 Terra     ~7-20x cheaper
The low end of each range is peak input, the high end is off-peak output, so where a run lands depends on the hour it runs and on how much of it is output. This compares API rates against API rates, so a fixed monthly subscription is not directly comparable.
Flash is a strong default for:
repository exploration
tests
docs
boilerplate
routine refactors
CI fixes
subagent loops
I would still escalate to a frontier Claude or GPT model for:
ambiguous architecture
hard debugging
security review
risky migrations
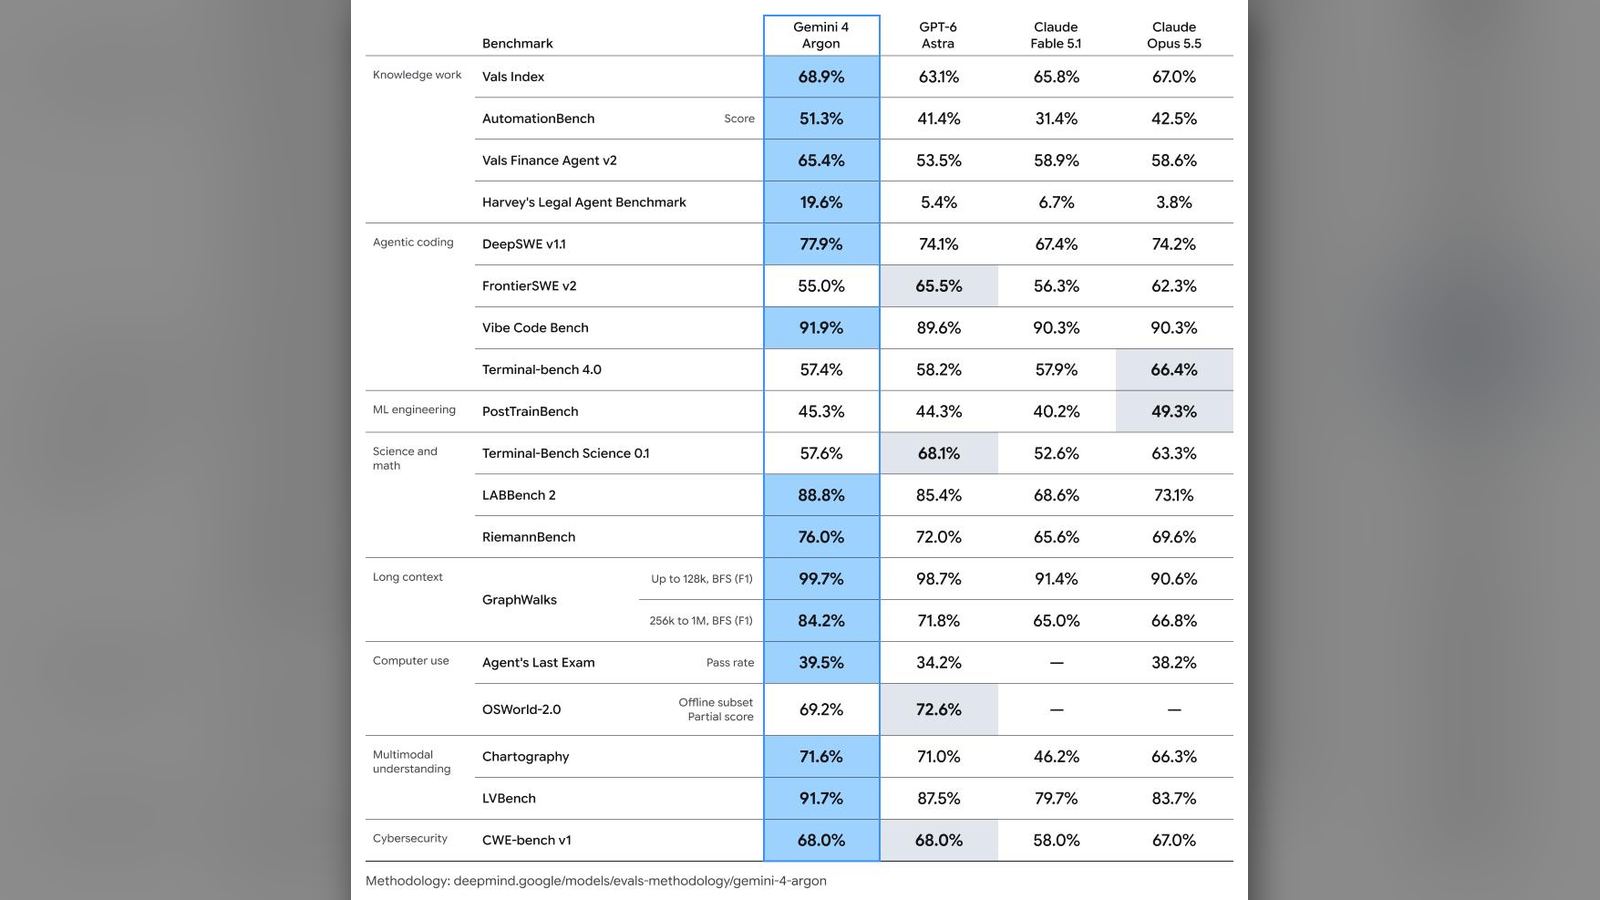
Neither side is universally weaker, and the split is where each one is worth its price.
Privacy
Do not casually send API keys, .env files, production credentials or large database dumps to a cloud model. For confidential code, prefer local inference or a provider whose retention policy matches your requirements.
When the model switched but the traffic did not
The interface says DeepSeek-Flash and the traffic still goes to the OpenAI Responses endpoint, with no OpenAI key in play. The model catalog changed and the provider section did not.
[model_providers.deepseek]
name = "deepseek"
base_url = "https://api.deepseek.com/"
wire_api = "responses"
experimental_bearer_token = "sk-YOUR_DEEPSEEK_API_KEY"
Close Codex, ChatGPT Desktop and VS Code completely and open them again, because picking the model in a running window does not reload the provider.
Reference links
Claude Code integration: https://api-docs.deepseek.com/quick_start/agent_integrations/claude_code/
Codex CLI integration: https://api-docs.deepseek.com/quick_start/agent_integrations/codex/
DeepSeek pricing: https://api-docs.deepseek.com/quick_start/pricing/
Claude pricing: https://platform.claude.com/docs/en/about-claude/pricing
OpenAI pricing: https://developers.openai.com/api/docs/pricing
Follow me for more on AI and Software Development:
khasky — LinkedIn / GitHub / Patreon / Bluesky / Mastodon / Medium / Devto
khaskydev — X / Threads / Instagram / Pinterest / Tumblr / Facebook / VK